Large language models can write, summarize, translate, and respond in ways that feel surprisingly human. But there is no magic inside the machine. There is mathematics, training data, and a great deal of computation.
I find these systems easier to understand when we look at the pieces one at a time. You do not need an advanced mathematics degree to follow the basic ideas. A few useful comparisons can take us a long way, as long as we remember where those comparisons stop.
Tokenization: chopping up words
Before a model can process text, a tokenizer breaks it into smaller units called tokens. A token might be a word, part of a word, punctuation, or another unit of text. Each token is assigned a numerical identifier.
Byte Pair Encoding, or BPE, is one approach to building these units. It allows words to be represented through combinations of smaller pieces rather than requiring a separate entry for every possible word.
Example: As an illustration, “unbelievable” could be split into “un,” “believ,” and “able.” The actual split depends on the tokenizer. Even spaces and punctuation can affect the result.
Why it matters: Tokenization is the bridge between human text and the numerical inputs a model uses. It also affects context limits and processing costs.
Embeddings: giving tokens a map
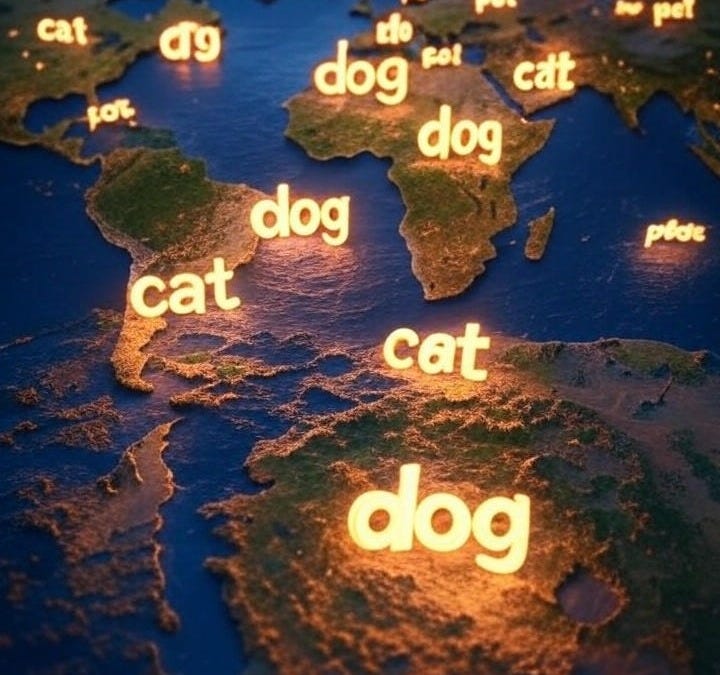
The model turns token identifiers into vectors: lists of numbers called embeddings. Think of a vector as a location on a very large map. Tokens used in similar ways can develop useful relationships in this numerical space.
The map comparison is helpful, but a real embedding may have hundreds or thousands of dimensions. It is not a simple three-dimensional GPS coordinate.
Example: “Cat” and “dog” may have related representations because they appear in similar contexts. The surrounding sentence then helps the model interpret a word such as “bank,” which could refer to money or the side of a river.
Why it matters: Embeddings provide a starting representation. Later layers use context to refine that representation, rather than treating each word as an isolated dictionary entry.
Transformers: connecting the context
The transformer architecture, introduced in 2017, made attention central to processing sequences. Self-attention helps a model combine information from different token positions.
How it works: In “The dog that ate the bone is happy,” the model can build a relationship between “dog” and “happy,” even though several words separate them.
At a high level, attention compares learned query and key vectors and uses the resulting weights to combine value vectors. This happens across multiple heads and layers, alongside other mathematical operations.
There is one important detail: a typical text-generating model does not see future tokens while predicting the next one. It attends to the allowed preceding context and generates its response one token at a time.
Why it matters: These connections help with translation, summarization, and other tasks where meaning depends on more than the nearest word.
Positional encoding: keeping things in order
“The dog chased the cat” is not the same as “The cat chased the dog.” A model needs information about order, not just the tokens themselves.
Position mechanisms provide that information. The original transformer used sine and cosine patterns. Other architectures use different methods, including rotary position representations.
Example: In “I am happy,” position information helps distinguish the first, second, and third tokens and how they relate to one another.
Why it matters: Order helps the model interpret grammar and relationships. It does not mean the model can handle an unlimited amount of text.
Learning by fixing mistakes
During next-token training, a model predicts a token and compares that prediction with the token in the training example. A loss function measures the mismatch. Backpropagation calculates how the parameters contributed to that loss, and an optimizer updates them.
Gradient descent is the general idea behind moving the parameters in a direction that reduces the loss. Optimizers such as Adam adapt those updates.
Example: If a training passage continues “The cat is sleeping,” the model is rewarded for assigning a higher probability to the observed continuation. A different continuation could still be valid English. The training target is what appeared in that example.
Why it matters: Repeating this process across many examples teaches patterns. Ordinary use of a chatbot does not necessarily update its model weights after each conversation.
Entropy: variety versus predictability
At each generation step, the model assigns probabilities to possible next tokens. Entropy measures uncertainty in that distribution. A concentrated distribution has lower entropy; a more spread-out one has higher entropy.
Temperature can change how sharply the model favors high-probability options when sampling. Higher settings often produce more varied output. Lower settings generally make the selection more predictable.
Example: A dragon story might benefit from more variation. A structured extraction task may benefit from more consistent output.
Why it matters: Variety can help creative work, but temperature is not a truth setting. A predictable answer can still be factually wrong.
Scaling: more capability, more trade-offs
Model size, training data, and computation all influence performance. Scaling laws describe observed relationships among these factors and training loss.
However, bigger is not automatically better for every use case. The balance matters. Research on compute-optimal training showed that a smaller model trained on more data could outperform much larger, less well-trained models under comparable training budgets.
Why it matters: The useful question is not simply “Which model is largest?” It is “Which model meets the task’s quality, cost, latency, and operating requirements?”
Avoiding overfitting: learn beyond the examples
Overfitting happens when a model fits its training data too closely and performs poorly on unseen examples. It is like a student memorizing the practice answers without learning the subject.
Regularization methods, such as weight decay and, where appropriate, dropout, can help. Data quality, training choices, and evaluation on held-out examples also matter.
Example: A model that performs well on familiar document templates may struggle when the layout changes. Testing only the familiar templates would hide that weakness.
Why it matters: We want performance that carries over to new cases. No single regularization technique guarantees that result.
Memory: holding on to the context
A model’s context window limits how much information it can process in one request. The limit is measured in tokens, not words, and depends on the model.
Conversation history included in the request can help it use earlier details. Application-level memory can store selected information and retrieve it later. Neither is the same as changing the model’s trained parameters.
Example: If an application supplies your earlier preference for science fiction, the model can use it when suggesting books. If that information is no longer in the context or retrieved memory, it may not be available.
Why it matters: A large context window does not guarantee perfect recall. Long conversations still need careful information management.
Multimodality: working across media
Some models can work with text, images, audio, or video. They use representations that allow information from these different formats to be processed together, although the architecture varies.
Example: Show a model a sunset photograph and ask it to describe the scene or write a poem inspired by it.
Why it matters: This opens up useful applications such as discussing charts, reading visual documents, and combining speech with images. It does not mean the model perceives or understands the world exactly as a person does.
Fine-tuning: adapting to a task
Fine-tuning continues training a pretrained model on selected examples. It can improve a particular style, format, or task behavior without training a new model from the beginning.
Some methods update many parameters. Parameter-efficient methods update a smaller set or add trainable components. Either way, the result needs testing for both improvements and regressions.
Example: A model can be adapted to draft documents in an organization’s preferred format. A qualified reviewer still needs to check legal or medical work.
Why it matters: Fine-tuning can make behavior more consistent. It does not automatically provide current information or guarantee that earlier capabilities are preserved.
Reinforcement learning: listening to people
Reinforcement Learning from Human Feedback, or RLHF, uses human preferences to help shape model behavior. In a common approach, people compare responses, those comparisons help train a reward model, and the language model is optimized against that signal.
Example: Reviewers may prefer a response that is clear, helpful, and considerate over one that is confusing or dismissive.
Why it matters: Feedback helps align behavior with what people want. It does not guarantee truth, fairness, or safety. Those still need explicit evaluation and controls.
Learning from a few examples
A model can often follow a new task pattern after seeing a few examples in its prompt. This is usually called few-shot or in-context learning.
Example: Show several examples of turning customer comments into a short summary with a category label. The model can then try the same format on a new comment.
That does not normally change the model’s weights. Meta-learning is a broader research area concerned with learning how to learn; the terms should not be treated as interchangeable.
Why it matters: Good examples can make a task clearer without a separate fine-tuning process.
Interpretability: understanding the system
Interpretability asks what is happening inside a model and how its components influence the output. Attention maps can show certain relationships between token positions, but they are not a complete explanation of a decision.
Example: A map may show a strong attention connection between “dog” and “happy.” That alone does not prove why the model produced a particular answer.
Why it matters: Useful understanding requires more than an attractive visualization. Testing, interventions, and careful analysis help us distinguish a plausible story from an actual explanation.
The future: capable and responsible AI
The mathematics behind language models is opening up new ways to work with language, images, and sound. I find that exciting. I also think we should be careful about describing these systems as if they think, learn, or remember exactly as humans do.
More capable models will not automatically become safer or fairer. Better training methods need to be matched with evaluation, security, human oversight, and sensible limits on what systems are allowed to do.
The challenge is to make AI useful without ignoring its costs, energy use, or potential for error. That is an engineering and leadership responsibility as much as a mathematical one.
Wrapping it up
Tokens, vectors, attention, probability, and optimization may sound technical, but each solves a practical problem. Together, they help turn human language into numerical patterns a model can learn from and use.
Understanding these pieces makes AI less mysterious. More importantly, it helps us ask better questions about where a model can help, where it may fail, and what we should verify before relying on it.